Monday, 29 December 2014

Chapter 7 : Accounting

Chapter 7 : Accounting

General Ledger Data
The general ledger (G/L) is a core foundation financial system because it ties
together the detailed information collected by the purchasing, payables (what
you owe to others), and receivables (what others owe you) subledgers or systems.
In this case study we’ll focus on the general ledger rather than the subledgers,
which would be handled as separate business processes and fact tables.
As we work through a basic design for G/L data, we discover, once again, that
two complementary schemas with periodic snapshot and transaction-grained
fact tables working together are required.
Financial analysts are constantly looking to streamline the processes for
period-end closing, reconciliation, and reporting of G/L results. While operational
G/L systems often support these requisite capabilities, they may be
cumbersome, especially if you’re not dealing with a modern G/L. In this chapter
we’ll focus on more easily analyzing the closed financial results rather than
facilitating the close. However, in many organizations, G/L trial balances are
loaded into the data warehouse to leverage the capabilities of the data warehouse’s
presentation area to find the needles in the G/L haystack and then
make the appropriate operational adjustments before the period ends.
The sample schema in Figure 7.1 supports the access and analysis of G/L
account balances at the end of each account period. It would be very useful for
many kinds of financial analysis, such as account rankings, trending patterns,

and period-to-period comparisons.


In general, to-date totals should be calculated, not stored in the fact table.

Role of OLAP and Packaged Analytic Solutions
Given the standard nature of G/L processing, purchasing a G/L package
rather than attempting to build one from scratch has been a popular route for
years. Nearly all the operational package providers also offer a complementary
analytic solution, sometimes in partnership with one of the multidimensional
OLAP vendors. In many cases these canned analyses based on the
cumulative experience of the vendor are a sound way to jump-start a financial
data warehouse implementation with potentially reduced cost and risk. The
analytic solutions often have tools to assist with the extraction and staging of
operational financial data, as well as tools to assist with analysis and interpretation.
However, as we discussed in Chapter 6, when leveraging packaged
solutions, we need to be cautious about avoiding stovepipe applications. One
could easily find oneself in a situation with separate financial, CRM, human
resources, and ERP packaged analytic solutions from as many different vendors,
none of which integrates with other internal data. We need to conform
dimensions across the entire data warehouse environment regardless of
whether we’re building our own solution or implementing packages. Packaged
analytic solutions can turbocharge your data warehouse implementation;
however, they do not alleviate the need for conformance. Most
organizations inevitably will rely on a combination of building, buying, and
integrating for a complete solution


The budget line item identifies the purpose of the proposed spending, such as
employee wages or office supplies. Typically, several levels of summarization
categories are associated with a budget line item. As we discussed in Chapter 5,
all the budget line items may not have the same number of levels in their summarization
hierarchy, such as when some have only a category roll-up but not
a subcategory. In this case we may populate the dimension attributes by replicating
the category name in the subcategory column to avoid having line items
roll up to a “Not Applicable” subcategory bucket. The budget line-item dimension
also would identify the budget year and budget version.
The effective month is the month during which the budget changes are posted.
The first entries for a given budget year would show the effective month when
the budget is first approved. If the budget is updated or modified as the budget
year gets underway, the effective months would occur during the budget
year. If we don’t adjust the budget at all throughout the year, then the only
entries would be the first ones when the budget is approved. This is what we
meant when we specified the grain to be the net change. It is critical that you
understand this point, or you won’t understand what is in this budget fact
table or how it is used.

Consolidated Fact Tables


When facts from multiple business processes are combined in a consolidated fact
table, they must live at the same level of granularity and dimensionality. Optimally, the
separate facts naturally live at a common grain. Otherwise, we are forced to eliminate
or aggregate some dimensions to support the one-to-one correspondence or keep
them in separate fact tables. Project teams should not create artificial facts or dimensions
in an attempt to force fit the consolidation of differently grained fact data

Chapter 6 : Customer Relationship Management

Chapter 6 : Customer Relationship Management

As data is created on the operational side of the CRM equation, we obviously
need to store and analyze the historical metrics resulting from our customer
interaction and transaction systems. Sounds familiar, doesn’t it? The data
warehouse sits at the core of CRM. It serves as the repository to collect and
integrate the breadth of customer information found in our operational systems,
as well as from external sources. The data warehouse is the foundation
that supports the panoramic 360-degree view of our customers, including customer
data from the following typical sources: transactional data, interaction
data (solicitations, call center), demographic and behavioral data (typically
augmented by third parties), and self-provided profile data.
Analytic CRM is enabled via accurate, integrated, and accessible customer
data in the warehouse. We are able to measure the effectiveness of decisions
made in the past in order to optimize future interactions. Customer data can be
leveraged to better identify up-sell and cross-sell opportunities, pinpoint inefficiencies,
generate demand, and improve retention. In addition, we can leverage
the historical, integrated data to generate models or scores that close the
loop back to the operational world. Recalling the major components of a warehouse
environment from Chapter 1, we can envision the model results pushed
back to where the relationship is operationally managed (for example, sales
rep, call center, or Web site), as illustrated in Figure 6.1. The model output can
translate into specific proactive or reactive tactics recommended for the next
point of customer contact, such as the appropriate next product offer or antiattrition
response. The model results also are retained in the data warehouse for

subsequent analysis.

Obviously, as the organization becomes more centered on the customer, so
must the data warehouse. CRM inevitably will drive change in the data warehouse.
Data warehouses will grow even more rapidly as we collect more and
more information about our customers, especially from front-office sources
such as the field force. Our data staging processes will grow more complicated
as we match and integrate data from multiple sources. Most important, the
need for a conformed customer dimension becomes even more paramount.

Packaged CRM
In response to the urgent need of business for CRM, project teams may be
wrestling with a buy versus build decision. In the long run, the build approach
may match the organization’s requirements better than the packaged application,
but the implementation likely will take longer and require more
resources, potentially at a higher cost. Buying a packaged application will
deliver a practically ready-to-go solution, but it may not focus on the integration
and interface issues needed for it to function in the larger IT context. Fortunately,
some providers are supporting common data interchange through
Extensible Markup Language (XML), publishing their data specifications so
that IT can extract dimension and fact data, and supporting customer-specific
conformed dimensions.

Customer Dimension
The conformed customer dimension is a critical element for effective CRM. A
well-maintained, well-deployed conforming customer dimension is the cornerstone
of sound customer-centric analysis.
The customer dimension is typically the most challenging dimension for any
data warehouse. In a large organization, the customer dimension can be
extremely deep (with millions of rows), extremely wide (with dozens or even
hundreds of attributes), and sometimes subject to rather rapid change. One
leading direct marketer maintains over 3,000 attributes about its customers.
Any organization that deals with the general public needs an individual
human being dimension. The biggest retailers, credit card companies, and
government agencies have monster customer dimensions whose sizes exceed
100 million rows. To further complicate matters, the customer dimension often
represents an amalgamation of data from multiple internal and external source
systems.
Dimension Outrigger


Dimension Outriggers for a Low-Cardinality Attribute Set
As we said in Chapter 2, a dimension is said to be snowflaked when the low-cardinality
columns in the dimension have been removed to separate normalized
tables that then link back into the original dimension table. Generally,
snowflaking is not recommended in a data warehouse environment because it
almost always makes the user presentation more complex, in addition to having
a negative impact on browsing performance. Despite this prohibition
against snowflaking, there are some situations where you should build a
dimension outrigger that has the appearance of a snowflaked table. Outriggers
have special characteristics that cause them to be permissible snowflakes.


In Figure 6.3, the dimension outrigger is a set of data from an external data
provider consisting of 150 demographic and socioeconomic attributes regarding
the customers’ county of residence. The data for all customers residing in a given
county is identical. Rather than repeating this large block of data for every customer
within a county, we opt to model it as an outrigger. There are several factors
that cause us to bend our no-snowflake rule. First of all, the demographic
data is available at a significantly different grain than the primary dimension
data (county versus individual customer). The data is administered and loaded
at different times than the rest of the data in the customer dimension. Also, we
really do save significant space in this case if the underlying customer dimension
is large. If you have a query tool that insists on a classic star schema with no
snowflakes, you can hide the outrigger under a view declaration.
Dimension outriggers are permissible, but they should be the exception rather than
the rule. A red warning flag should go up if your design is riddled with outriggers;
you may have succumbed to the temptation to overly normalize the design.

Large Changing Customer Dimensions
Multimillion-row customer dimensions present two unique challenges that
warrant special treatment. Even if a clean, flat dimension table has been implemented,
it generally takes too long to constrain or browse among the relationships
in such a big table. In addition, it is difficult to use our tried-and-true
techniques from Chapter 4 for tracking changes in these large dimensions. We
probably don’t want to use the type 2 slowly changing dimension technique
and add more rows to a customer dimension that already has millions of rows
in it. Unfortunately, huge customer dimensions are even more likely to change
than moderately sized dimensions. We sometimes call this situation a rapidly
changing monster dimension!

minidimension
Business users often want to track the myriad of customer attribute changes.
In some businesses, tracking change is not merely a nice-to-have analytic capability.
Insurance companies, for example, must update information about their
customers and their specific insured automobiles or homes because it is critical
to have an accurate picture of these dimensions when a policy is approved
or claim is made.
Fortunately, a single technique comes to the rescue to address both the browsing-
performance and change-tracking challenges. The solution is to break off
frequently analyzed or frequently changing attributes into a separate dimension,
referred to as a minidimension. For example, we could create a separate
minidimension for a package of demographic attributes, such as age, gender,
number of children, and income level, presuming that these columns get used
extensively. There would be one row in this minidimension for each unique
combination of age, gender, number of children, and income level encountered
in the data, not one row per customer. These columns are the ones that
are analyzed to select an interesting subset of the customer base. In addition,
users want to track changes to these attributes. We leave behind more constant
or less frequently queried attributes in the original huge customer table.
Sample rows for a demographic minidimension are illustrated in Table 6.3.
When creating the minidimension, continuously variable attributes, such as
income and total purchases, should be converted to banded ranges. In other
words, we force the attributes in the minidimension to take on a relatively small
number of discrete values. Although this restricts use to a set of predefined
bands, it drastically reduces the number of combinations in the minidimension.
If we stored income at a specific dollar and cents value in the minidimension,
when combined with the other demographic attributes, we could end up with as
many rows in the minidimension as in the main customer dimension itself. The
use of band ranges is probably the most significant compromise associated
with the minidimension technique because once we decide on the value bands,
it is quite impractical to change to a different set of bands at a later time. If users
insist on access to a specific raw data value, such as a credit bureau score that is
updated monthly, it also should be included in the fact table, in addition to
being represented as a value band in the demographic minidimension.


Values are available in mididimension as well as in fact
Every time we build a fact table row, we include two foreign keys related to the
customer: the regular customer dimension key and the minidimension demographics
key. As shown in Figure 6.4, the demographics key should be part of
the fact table’s set of foreign keys in order to provide efficient access to the fact
table through the demographics attributes. This design delivers browsing and
constraining performance benefits by providing a smaller point of entry to the
facts. Queries can avoid the huge customer dimension table altogether unless
attributes from that table are constrained.


When the demographics key participates as a foreign key in the fact table,
another benefit is that the fact table serves to capture the demographic profile
changes. Let’s presume that we are loading data into a periodic snapshot fact
table on a monthly basis. Referring back to our sample demographic minidimension
sample rows in Table 6.3, if one of our customers, John Smith, was 24
years old with an income of $24,000, we’d begin by assigning demographics
key 2 when loading the fact table. If John has a birthday several weeks later,
we’d assign demographics key 18 when the fact table was next loaded. The
demographics key on the earlier fact table rows for John would not be
changed. In this manner, the fact table tracks the age change. We’d continue to
assign demographics key 18 when the fact table is loaded until there’s another
change in John’s demographic profile. If John receives a raise to $26,000 several
months later, a new demographics key would be reflected in the next fact
table load. Again, the earlier rows would be unchanged. Historical demographic
profiles for each customer can be constructed at any time by referring
to the fact table and picking up the simultaneous customer key and its contemporary
demographics key, which in general will be different from the most
recent demographics key.
The minidimension terminology refers to when the demographics key is part of the
fact table composite key; if the demographics key is a foreign key in the customer dimension,
we refer to it as an outrigger.


The best approach for efficiently browsing and tracking changes of key attributes in
really huge dimensions is to break off one or more minidimensions from the dimension
table, each consisting of small clumps of attributes that have been administered
to have a limited number of values.

Variable-Width Attribute Set
When using external prospect lists, we often are permitted only a one-time use
of the list and don’t have the legal right to store the prospect information internally.
However, if we’ve generated our own prospect information, it certainly
can be stored in the data warehouse. Let’s assume that we’re capturing metrics,
perhaps associated with solicitation or quote-generation events that apply to
both prospects and customers. We could store the prospects and customers
together in a single contact dimension; however, there is a significant disparity
between the numbers of attributes for prospective versus customer contacts. As
illustrated in Figure 6.6, we may know only a handful of identification and location
attributes about our prospects. On the other hand, we may know 50 additional
attributes for a customer, covering purchase, payment, credit and service
behaviors, directly elicited profile attributes, and third-party purchased demographic
attributes. In the world of electronic retailing, we can equate prospects
to be the anonymous Web site visitors as opposed to our registered customers

If we’re dealing with a database platform that supports variable-width rows,
such as Oracle, we may be able to build a single dimension with the full complement
of attributes if the total attributes list is not too long; in some of these
cases, we don’t need to worry about all the prospects’ null columns because
they take up virtually zero disk space. However, if we have a fixed-width database,
or if the attributes list is very long, we are uncomfortable with all the
empty columns for the prospects. In this case, as shown in Figure 6.6, we break
the dimension into a 10-million-row base dimension table consisting of attributes
that are common to both prospects and customers, along with a 1-millionrow
customer minidimension that contains the additional attributes we know
about our customers. Again, we include two foreign keys in the fact table.
Nine of ten fact table rows would join to an empty customer row in the
extended customer minidimension.
behaviour customer group
The secret to building complex behavioral study group queries is to capture the keys
of the customers or products whose behavior you are tracking. You then use the captured
keys to constrain other fact tables without having to rerun the original behavior
analysis.


Variable-Depth Hierarchies
Representing an arbitrary, ragged organization hierarchy is an inherently difficult
task in a relational environment. For example, we may want to report the
revenues for a set of commercial customers who have intricate relationships
with each other, such as in Figure 6.8. Each square on the diagram represents
an individual customer entity connected in an organizational tree. The illustrated
organization has four levels; other customer organizations may have
one, ten, or more levels. Let’s assume that we sell our products or services to
any of these commercial customers. Thus the customer dimension rows can
play the role of parent as well as child. We may want to look at the customers
and their sales revenue individually. At other times, we may want to summarize
revenue to any node in the overall organizational tree.
Instead of using a recursive pointer, we insert a bridge table between the customer
dimension and fact tables, as depicted in Figure 6.9. The bridge table has
been called a helper or associative table in the past, but going forward, we’ll consistently
use the bridge terminology. Use of the bridge table is optional; neither
the customer dimension table nor the fact table has to be modified in any way.
If the bridge table is left out, the customer dimension table joins to the fact
table in the usual way. We can report revenue by customer, but we’re unable to
navigate the organization hierarchy. When the bridge table is inserted between
the customer dimension and fact tables, we’re able to analyze revenue results
at any hierarchical level using standard SQL, albeit via a more complicated
presentation.
The bridge table contains one row for each pathway in Figure 6.8 from a customer
entity to each subsidiary beneath it, as well as a row for the zero-length pathway
from a customer to itself. Each pathway row contains the customer key of the parent
roll-up entity, the customer key of the subsidiary entity, the number of levels
between the parent and the subsidiary, a bottom-most flag that identifies a subsidiary
with no further nodes beneath it, and finally, a top-most flag to indicate
that there are no further nodes above the parent. The sample bridge table rows
corresponding to the hierarchy in Figure 6.8 are shown as in Table 6.4.


When we want to descend the organization hierarchy, we join the tables
together as shown in Figure 6.9. We can now constrain the customer table to a
particular parent customer and request any aggregate measure of all the subsidiaries
at or below that customer. We can use the “# of Levels from Parent”
column in the organization bridge table to control the depth of the analysis.
Constraining to a value of 1 would give all the direct subsidiaries of the customer.
A value greater than zero would give all subsidiary customers but not
the original parent. We can use the “Bottom Flag” column to jump directly to all
the bottom-most customer entities but omit all higher-level customer entities.
If we wanted
to sum up revenue in the fact table for a given customer and all its subsidiaries,
the SQL code would look something like the following:


We can request all the revenue from the organizations associated with many
parents at once, but we have to get the subsidiary keys distinctly or risk double
counting. In the following example we retrieve the January 2002 revenue
from all organizations whose parents are located in San Francisco. The SQL
code is messier, but it works for both unique and multiple parent customers.


Be very careful when simultaneously joining a single dimension table to two fact
tables of different cardinality. In many cases, relational systems will return the
wrong answer. A similar problem arises when joining two fact tables of different
granularity together directly.
Consider the case in which we have a fact table of customer solicitations and
another fact table with the customer responses resulting both from the solicitations
and other independent sources. There is a one-to-many relationship
between customer and solicitation and another one-to-many relationship
between customer and response. The solicitation and response fact tables have
different cardinalities; in other words, not every solicitation results in a
response (unfortunately for the marketing department), and some responses
are received for which there is no solicitation. Simultaneously joining the solicitation
fact table to the customer dimension, which is in turn joined to the
response fact table, does not return the correct answer in a relational DBMS
because of the cardinality differences. Fortunately, this problem is easily
avoided. We simply issue multipass SQL code to query the solicitation and
response tables in separate queries and then outer join the two answer sets.
The multipass approach has additional benefits in terms of better controlling
performance parameters, in addition to supporting queries that combine data
from fact tables in different physical locations.

Chapter 5 : Order Management

Chapter 5 : Order Management

Order management consists of several critical business processes, including
order, shipment, and invoice processing. These processes spawn important
business metrics, such as sales volume and invoice revenue, that are key performance
indicators for any organization that sells products or services to
others.


It is natural and common, especially for customer-oriented dimensions, for a dimension
to simultaneously support multiple independent hierarchies. The hierarchies
may have different numbers of levels. Drilling up and drilling down within each of
these hierarchies must be supported in a data warehouse.

The one-to-one or many-to-one relationship may turn out to be a many-tomany
relationship. As we discussed earlier, if the many-to-many relationship
is an exceptional condition, then we may still be tempted to combine
the sales rep attributes into the ship-to dimension, knowing that we’d need
to treat these rare many-to-many occurrences by issuing another surrogate
ship-to key.
If the relationship between sales rep and customer ship-to varies over time
or under the influence of a fourth dimension such as product, then the
combined dimension is in reality some kind of fact table itself! In this
case, we’d likely create separate dimensions for the sales rep and the customer
ship-to.
If the sales rep and customer ship-to dimensions participate independently
in other business process fact tables, we’d likely keep the dimensions
separate. Creating a single customer ship-to dimension with sales rep

attributes exclusively around orders data may make some of the other

Role Playing Dimension
Role-playing in a data warehouse occurs when a single dimension simultaneously
appears several times in the same fact table. The underlying dimension may exist as
a single physical table, but each of the roles should be presented to the data access
tools in a separately labeled view.


Deal Dimension
The deal dimension is similar to the promotion dimension from Chapter 2. The
deal dimension describes the incentives that have been offered to the customer
that theoretically affect the customers’ desire to purchase products. This
dimension is also sometimes referred to as the contract. As shown in Figure 5.4,
the deal dimension describes the full combination of terms, allowances, and

incentives that pertain to the particular order line item.


Degenerate Dimension for Order Number
Each line item row in the orders fact table includes the order number as a
degenerate dimension, as we introduced in Chapter 2. Unlike a transactional
parent-child database, the order number in our dimensional models is not tied
to an order header table. We have stripped all the interesting details from the
order header into separate dimensions such as the order date, customer ship-to,
and other interesting fields. The order number is still useful because it allows us
to group the separate line items on the order. It enables us to answer such questions
as the average number of line items on an order. In addition, the order
number is used occasionally to link the data warehouse back to the operational
world. Since the order number is left sitting by itself in the fact table without
joining to a dimension table, it is referred to as a degenerate dimension.
Degenerate dimensions typically are reserved for operational transaction identifiers.
They should not be used as an excuse to stick a cryptic code in the fact table without
joining to a descriptive decode in a dimension table.

Junk Dimensions
When we’re confronted with a complex operational data source, we typically
perform triage to quickly identify fields that are obviously related to dimensions,
such as date stamps or attributes. We then identify the numeric measurements
in the source data. At this point, we are often left with a number of
miscellaneous indicators and flags, each of which takes on a small range of discrete
values. The designer is faced with several rather unappealing options,
including:
Leave the flags and indicators unchanged in the fact table row. This could
cause the fact table row to swell alarmingly. It would be a shame to create a
nice tight dimensional design with five dimensions and five facts and then
leave a handful of uncompressed textual indicator columns in the row
Make each flag and indicator into its own separate dimension. Doing so
could cause our 5-dimension design to balloon into a 25-dimension design.
Strip out all the flags and indicators from the design. Of course, we ask the
obligatory question about removing these miscellaneous flags because they
seem rather insignificant, but this notion is often vetoed quickly because
someone might need them. It is worthwhile to examine this question carefully.
If the indicators are incomprehensible, noisy, inconsistently populated,
or only of operational significance, they should be left out
An appropriate approach for tackling these flags and indicators is to study
them carefully and then pack them into one or more junk dimensions.
A junk dimension is a convenient grouping of typically low-cardinality flags and indicators.
By creating an abstract dimension, we remove the flags from the fact table
while placing them into a useful dimensional framework.


We’ve illustrated sample rows from an order indicator dimension in Figure 5.5. A
subtle issue regarding junk dimensions is whether you create rows for all the
combinations beforehand or create junk dimension rows for the combinations as
you actually encounter them in the data. The answer depends on how many possible
combinations you expect and what the maximum number could be. Generally,
when the number of theoretical combinations is very high and you don’t
think you will encounter them all, you should build a junk dimension row at
extract time whenever you encounter a new combination of flags or indicators


Header and Line Item Facts with Different Granularity
It is quite common in parent-child transaction databases to encounter facts of differing
granularity. On an order, for example, there may be a shipping charge that
applies to the entire order that isn’t available at the individual product-level line
item in the operational system. The designer’s first response should be to try to
force all the facts down to the lowest level. We strive to flatten the parent-child
relationship so that all the rows are at the child level, including facts that are captured
operationally at the higher parent level, as illustrated in Figure 5.7. This procedure
is broadly referred to as allocating. Allocating the parent order facts to the
child line-item level is critical if we want the ability to slice and dice and roll up all
order facts by all dimensions, including product, which is a common requirement


We shouldn’t mix fact granularities (for example, order and order line facts) within a
single fact table. Instead, we need to either allocate the higher-level facts to a more
detailed level or create two separate fact tables to handle the differently grained
facts. Allocation is the preferred approach. Optimally, a finance or business team
(not the data warehouse team) spearheads the allocation effort.

Invoice Transaction
In the shipment invoice fact table we can see all the company’s products, all
the customers, all the contracts and deals, all the off-invoice discounts and
allowances, all the revenue generated by customers purchasing products, all
the variable and fixed costs associated with manufacturing and delivering
products (if available), all the money left over after delivery of product (contribution),
and customer satisfaction metrics such as on-time shipment.

For any company that ships products to customers or bills customers for services rendered,
the optimal place to start a data warehouse typically is with invoices. We often
refer to the data resulting from invoicing as the most powerful database because it
combines the company’s customers, products, and components of profitability.


Extended gross invoice amount. This is also know as extended list price
because it is the quantity shipped multiplied by the list unit price.
Extended allowance amount. This is the amount subtracted from the
invoice-line gross amount for deal-related allowances. The allowances are
described in the adjoined deal dimension. The allowance amount is often
called an off-invoice allowance
Extended discount amount. This is the amount subtracted on the invoice for
volume or payment-term discounts. The explanation of which discounts
are taken is also found in the deal dimension row that points to this fact
table row
All allowances and discounts in this fact table are represented at the line
item level. As we discussed earlier, some allowances and discounts may be
calculated operationally at the invoice level, not the line-item level. An
effort should be made to allocate them down to the line item. An invoice
P&L statement that does not include the product dimension poses a serious
limitation on our ability to present meaningful P&L slices of the business.
Extended net invoice amount. This is the amount the customer is expected to
pay for this line item before tax. It is equal to the gross invoice amount less
the allowances and discounts.

However, there are times when users are more interested in analyzing the
entire order fulfillment pipeline. They want to better understand product
velocity, or how quickly products move through the pipeline. The accumulating
snapshot fact table provides us with this perspective of the business, as
illustrated in Figure 5.10. It allows us to see an updated status and ultimately
the final disposition of each order


The accumulating snapshot complements our alternative perspectives of the
pipeline. If we’re interested in understanding the amount of product flowing
through the pipeline, such as the quantity ordered, produced, or shipped, we rely
on transaction schemas that monitor each of the pipeline’s major spigots. Periodic
snapshots give us insight into the amount of product sitting in the pipeline, such
as the backorder or finished goods inventories, or the amount of product flowing
through a spigot during a predefined time period. The accumulating snapshot
helps us better understand the current state of an order, as well as product movement
velocities to identify pipeline bottlenecks and inefficiencies.
We notice immediately that the accumulating snapshot looks different from
the other fact tables we’ve designed thus far. The reuse of conformed dimensions
is to be expected, but the number of date and fact columns is larger than
we’ve seen in the past. We capture a large number of dates and facts as the
order progresses through the pipeline. Each date represents a major milestone
of the fulfillment pipeline. We handle each of these dates as dimension roles by
creating either physically distinct tables or logically distinct views. It is critical
that a surrogate key is used for these date dimensions rather than a literal SQL
date stamp because many of the fact table date fields will be “Unknown” or
“To be determined” when we first load the row. Obviously, we don’t need to
declare all the date fields in the fact table’s primary key.
The fundamental difference between accumulating snapshots and other fact
tables is the notion that we revisit and update existing fact table rows as more
information becomes available. The grain of an accumulating snapshot fact
table is one row per the lowest level of detail captured as the pipeline is
entered. In our example, the grain would equal one row per order line item.
However, unlike the order transaction fact table we designed earlier with the
same granularity, the fact table row in the accumulating snapshot is modified
while the order moves through the pipeline as more information is collected
from every stage of the lifecycle.


Accumulating snapshots typically have multiple dates in the fact table representing the
major milestones of the process. However, just because a fact table has several dates
doesn’t dictate that it is an accumulating snapshot. The primary differentiator of an accumulating
snapshot is that we typically revisit the fact rows as activity takes place

Packaging all the facts and conversion factors together in the same fact table row
provides the safest guarantee that these factors will be used correctly. The converted
facts are presented in a view(s) to the users.


Beyond the Rear-View Mirror
Much of what we’ve discussed in this chapter focuses on effective ways to
analyze historical product movement performance. People sometimes refer to
these as rear-view mirror metrics because they allow us to look backward and
see where we’ve been.

Transaction Grain Real-Time Partition
If the static data warehouse fact table has a transaction grain, then it contains
exactly one record for each individual transaction in the source system from
the beginning of recorded history. If no activity occurs in a time period, there
are no transaction records. Conversely, there can be a blizzard of closely
related transaction records if the activity level is high. The real-time partition
has exactly the same dimensional structure as its underlying static fact table. It
only contains the transactions that have occurred since midnight, when we
loaded the regular data warehouse tables. The real-time partition may be completely
unindexed both because we need to maintain a continuously open
window for loading and because there is no time series (since we only keep
today’s data in this table). Finally, we avoid building aggregates on this table
because we want a minimalist administrative scenario during the day.
We attach the real-time partition to our existing applications by drilling across
from the static fact table to the real-time partition. Time-series aggregations
(for example, all sales for the current month) will need to send identical
queries to the two fact tables and add them together.
Forget indexes, except
for a B-Tree index on the fact table primary key to facilitate the most efficient
loading. Forget aggregations too. Our real-time partition can remain biased
toward very fast loading performance but at the same time provide speedy
query performance.
Periodic Snapshot Real-Time Partition
If the static data warehouse fact table has a periodic grain (say, monthly), then
the real-time partition can be viewed as the current hot-rolling month. Suppose
that we are working for a big retail bank with 15 million accounts. The static fact
table has the grain of account by month. A36-month time series would result in
540 million fact table records. Again, this table would be indexed extensively
and supported by aggregates to provide good query performance. The real-time
partition, on the other hand, is just an image of the current developing month,
updated continuously as the month progresses. Semiadditive balances and fully
additive facts are adjusted as frequently as they are reported. In a retail bank, the
core fact table spanning all account types is likely to be quite narrow, with perhaps
4 dimensions and 4 facts, resulting in a real-time partition of 480 MB. The
real-time partition again can be pinned in memory.
Accumulating Snapshot Real-Time Partition
Accumulating snapshots are used for short-lived processes such as orders and
shipments. A record is created for each line item on the order or shipment. In
the main fact table this record is updated repeatedly as activity occurs. We create
the record for a line item when the order is first placed, and then we update
it whenever the item is shipped, delivered to the final destination, paid for, or
maybe returned. Accumulating snapshot fact tables have a characteristic set of
date foreign keys corresponding to each of these steps
Queries against an accumulating snapshot with a real-time partition need to
fetch the appropriate line items from both the main fact table and the partition
and can either drill across the two tables by performing a sort merge (outer
join) on the identical row headers or perform a union of the rows from the two
tables, presenting the static view augmented with occasional supplemental
rows in the report representing today’s hot activity.
In this section we have made a case for satisfying the new real-time requirement
with specially constructed but nevertheless familiar extensions to our
existing fact tables. If you drop all the indexes (except for a basic B-Tree index
for updating) and aggregations on these special new tables and pin them in
memory, you should be able to get the combined update and query performance
needed.

Chapter 4 : Procruments

Chapter 4 : Procruments

Type 1: Overwrite the Value
With the type 1 response, we merely overwrite the old attribute value in the
dimension row, replacing it with the current value. In so doing, the attribute
always reflects the most recent assignment.

The type 1 response is easy to implement, but it does not maintain any history of
prior attribute values.

Before we leave the topic of type 1 changes, there’s one more easily overlooked
catch that you should be aware of. When we used a type 1 response to deal
with the relocation of IntelliKidz, any preexisting aggregations based on the
department value will need to be rebuilt. The aggregated data must continue
to tie to the detailed atomic data, where it now appears that IntelliKidz has
always rolled up into the Strategy department.

Type 2: Add a Dimension Row
We made the claim earlier in this book that one of the primary goals of the data
warehouse was to represent prior history correctly. A type 2 response is the
predominant technique for supporting this requirement when it comes to
slowly changing dimensions.
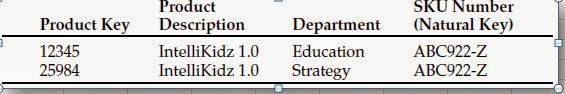
Using the type 2 approach, when IntelliKidz’s department changed, we issue
a new product dimension row for IntelliKidz to reflect the new department
attribute value. We then would have two product dimension rows for IntelliKidz,
such as the following:


Now we see why the product dimension key can’t be the SKU number natural
key. We need two different product surrogate keys for the same SKU or physical
barcode. Each of the separate surrogate keys identifies a unique product
attribute profile that was true for a span of time. With type 2 changes, the fact
table is again untouched. We don’t go back to the historical fact table rows to
modify the product key.
If we constrain only on the department attribute, then we very precisely differentiate
between the two product profiles. If we constrain only on the product
description, that is, IntelliKidz 1.0, then the query automatically will fetch
both IntelliKidz product dimension rows and automatically join to the fact
table for the complete product history. If we need to count the number of products
correctly, then we would just use the SKU natural key attribute as the
basis of the distinct count rather than the surrogate key. The natural key field
becomes a kind of reliable glue that holds the separate type 2 records for a single
product together. Alternatively, a most recent row indicator might be
another useful dimension attribute to allow users to quickly constrain their
query to only the current profiles.
Since the type 2 technique spawns new dimension rows, one downside of this
approach is accelerated dimension table growth. Hence it may be an inappropriate
technique for dimension tables that already exceed a million rows.

Type 3: Add a Dimension Column
In our software example, let’s assume that there is a legitimate business need
to track both the old and new values of the department attribute both forward
and backward for a period of time around the change. With a type 3 response,
we do not issue a new dimension row, but rather we add a new column to capture
the attribute change. In the case of IntelliKidz, we alter the product
dimension table to add a prior department attribute. We populate this new column
with the existing department value (Education). We then treat the department
attribute as a type 1 response, where we overwrite to reflect the current
value (Strategy). All existing reports and queries switch over to the new
department description immediately, but we can still report on the old department
value by querying on the prior department attribute.


The type 3 slowly changing dimension technique allows us to see new and historical
fact data by either the new or prior attribute values
Atype 3 response is inappropriate if you want to track the impact of numerous
intermediate attribute values.

Hybrid Slowly Changing Dimension Techniques


Each sales rep dimension row would include all prior district assignments.
The business user could choose to roll up the sales facts with any of the five
district maps. If a sales rep were hired in 2000, the dimension attributes for
1998 and 1999 would contain values along the lines of “Not Applicable.”
We label the most recent assignment as “Current District.” This attribute will
be used most frequently; we don’t want to modify our existing queries and
reports to accommodate next year’s change. When the districts are redrawn
next, we’d alter the table to add a district 2002 attribute. We’d populate this
column with the current district values and then overwrite the current
attribute with the 2003 district assignments.


In this manner we’re able to use the historical attribute to segment history and
see facts according to the departmental roll-up at that point in time. Meanwhile,
the current attribute rolls up all the historical fact data for product keys
12345 and 25984 into the current department assignment. If IntelliKidz were
then moved into the Critical Thinking software department, our product table
would look like the following:


With this hybrid approach, we issue a new row to capture the change (type
2) and add a new column to track the current assignment (type 3), where
subsequent changes are handled as a type 1 response. Someone once suggested
that we refer to this combo approach as type 6 (2 + 3 + 1). This technique
allows us to track the historical changes accurately while also
supporting the ability to roll up history based on the current assignments.
We could further embellish (and complicate) this strategy by supporting
additional static department roll-up structures, in addition to the current
department, as separate attributes.

More Rapidly Changing Dimensions
In this chapter we’ve focused on the typically rather slow, evolutionary
changes to our dimension tables. What happens, however, when the rate of
change speeds up? If a dimension attribute changes monthly, then we’re no
longer dealing with a slowly changing dimension that can be handled reasonably
with the techniques just discussed. One powerful approach for handling
more rapidly changing dimensions is to break off these rapidly changing
attributes into one or more separate dimensions. In our fact table we would
then have two foreign keys—one for the primary dimension table and another
for the rapidly changing attribute(s). These dimension tables would be associated
with one another every time we put a row in the fact table.

Chapter 3 : Inventory

Chapter 3 : Inventory


Semiadditive Facts
We stressed the importance of fact additivity in Chapter 2. When we modeled
the flow of product past a point at the checkout cash register, only the products
that actually sold were measured. Once a product was sold, it couldn’t be
counted again in a subsequent sale. This made most of the measures in the
retail sales schema perfectly additive across all dimensions.
In the inventory snapshot schema, the quantity on hand can be summarized
across products or stores and result in a valid total. Inventory levels, however,
are not additive across dates because they represent snapshots of a level or balance
at one point in time. It is not possible to tell whether yesterday’s inventory
is the same or different from today’s inventory solely by looking at
inventory levels. Because inventory levels (and all forms of financial account
balances) are additive across some dimensions but not all, we refer to them as
semiadditive facts.
The semiadditive nature of inventory balance facts is even more understandable
if we think about our checking account balances. On Monday, let’s presume
that you have $50 in your account. On Tuesday, the balance remains
unchanged. On Wednesday, you deposit another $50 into your account so that
the balance is now $100. The account has no further activity through the end of
the week. On Friday, you can’t merely add up the daily balances during the
week and declare that your balance is $400 (based on $50 + 50 + 100 + 100 +
100). The most useful way to combine account balances and inventory levels
across dates is to average them (resulting in an $80 average balance in the
checking example). We are all familiar with our bank referring to the average
daily balance on our monthly account summary.
All measures that record a static level (inventory levels, financial account balances,
and measures of intensity such as room temperatures) are inherently nonadditive
across the date dimension and possibly other dimensions. In these cases, the measure
may be aggregated usefully across time, for example, by averaging over the
number of time periods.
Drill Across
In Chapters 1 and 2 we modeled data from several processes of the value
chain. While separate fact tables in separate data marts represent the data from
each process, the models share several common business dimensions, namely,
date, product, and store. We’ve logically represented this dimension sharing in
Figure 3.6. Using shared, common dimensions is absolutely critical to designing
data marts that can be integrated. They allow us to combine performance
measurements from different processes in a single report. We use multipass
SQL to query each data mart separately, and then we outer join the query
results based on a common dimension attribute. This linkage, often referred to
as drill across, is straightforward if the dimension table attributes are identical


Buss Architecture
The word bus is an old term from the electrical power industry that is now
used commonly in the computer industry. A bus is a common structure to
which everything connects and from which everything derives power. The bus
in your computer is a standard interface specification that allows you to plug
in a disk drive, CD-ROM, or any number of other specialized cards or devices.
Because of the computer’s bus standard, these peripheral devices work
together and usefully coexist, even though they were manufactured at different
times by different vendors.
By defining a standard bus interface for the data warehouse environment, separate
data marts can be implemented by different groups at different times. The separate
data marts can be plugged together and usefully coexist if they adhere to the standard

The bus architecture is independent of technology and the database platform.
All flavors of relational and online analytical processing (OLAP)-based data
marts can be full participants in the data warehouse bus if they are designed
around conformed dimensions and facts. Data warehouses will inevitably
consist of numerous separate machines with different operating systems and
database management systems (DBMSs). If designed coherently, they will
share a uniform architecture of conformed dimensions and facts that will
allow them to be fused into an integrated whole.


The major responsibility of the centralized dimension authority is to establish, maintain,
and publish the conformed dimensions to all the client data marts.


gross margin return on inventory (GMROI,pronounced “jem-roy”)
Although this formula looks complicated, the idea behind GMROI is simple. By
multiplying the gross margin by the number of turns, we create a measure of the
effectiveness of our inventory investment. A high GMROI means that we are
moving the product through the store quickly (lots of turns) and are making
good money on the sale of the product (high gross margin). Alow GMROI means
that we are moving the product slowly (low turns) and aren’t making very much
money on it (low gross margin). The GMROI is a standard metric used by inventory
analysts to judge a company’s quality of investment in its inventory.
If we want to be more ambitious than our initial design in Figure 3.2, then we
should include the quantity sold, value at cost, and value at the latest selling
price columns in our snapshot fact table, as illustrated in Figure 3.3. Of course,
if some of these metrics exist at different granularity in separate fact tables, a
requesting application would need to retrieve all the components of the
GMROI computation at the same level.
Notice that quantity on hand is semiadditive but that the other measures in
our advanced periodic snapshot are all fully additive across all three dimensions.
The quantity sold amount is summarized to the particular grain of the
fact table, which is daily in this case. The value columns are extended, additive
amounts. We do not store GMROI in the fact table because it is not additive.
We can calculate GMROI from the constituent columns across any number of
fact rows by adding the columns up before performing the calculation, but we
are dead in the water if we try to store GMROI explicitly because we can’t usefully
combine GMROIs across multiple rows.


Remember that there’s more to life than transactions alone. Some form of snapshot
table to give a more cumulative view of a process often accompanies a transaction
fact table.

Let’s assume that the inventory goes through a series of well-defined events or
milestones as it moves through the warehouse, such as receiving, inspection,
bin placement, authorization to sell, picking, boxing, and shipping. The philosophy
behind the accumulating snapshot fact table is to provide an updated
status of the product shipment as it moves through these milestones. Each fact
table row will be updated until the product leaves the warehouse. As illustrated
in Figure 3.5, the inventory accumulating snapshot fact table with its
multitude of dates and facts looks quite different from the transaction or periodic
snapshot schemas.


The rows of the bus matrix correspond to data marts. You should create separate
matrix rows if the sources are different, the processes are different, or if the matrix
row represents more than what can reasonably be tackled in a single implementation
iteration.
Creating the data warehouse bus matrix is one of the most important up-front deliverables
of a data warehouse implementation. It is a hybrid resource that is part technical
design tool, part project management tool, and part communication tool.


It goes without saying that it is unacceptable to build separate data marts that
ignore a framework to tie the data together. Isolated, independent data marts
are worse than simply a lost opportunity for analysis. They deliver access to
irreconcilable views of the organization and further enshrine the reports that
cannot be compared with one another. Independent data marts become legacy
implementations in their own right; by their very existence, they block the
development of a coherent warehouse environment.

Conformed Fact
Revenue, profit, standard prices, standard costs, measures of quality, measures
of customer satisfaction, and other key performance indicators (KPIs) are facts
that must be conformed. In general, fact table data is not duplicated explicitly
in multiple data marts. However, if facts do live in more than one location,
such as in first-level and consolidated marts, the underlying definitions and
equations for these facts must be the same if they are to be called the same
thing. If they are labeled identically, then they need to be defined in the same
dimensional context and with the same units of measure from data mart to
data mart.